DeepSeek V4.1 Flash Head to Head: 4x CMP 170HX vs Mac Studio M5 Ultra
Nov 11, 2026 · Reclaimed Node · 6 min read
The short version
Racing side by side on DeepSeek V4.1 Flash, four CMP 170HX mining cards beat a Mac Studio M5 Ultra at every test. For one user they write 2.6 to 2.9 times faster (120 to 128 tokens/sec against 42 to 49) and read prompts 6 to 7 times faster. With 16 users the gap holds: the CMP box puts out 2.4 to 4.0 times as many tokens in total.
The two machines did not run the same file. The Mac ran a 2-bit build with its Engram tables on the SSD and no speculative decoding, so this is a race between two practical setups for the same model. The last section lays out how the next run brings the Mac closer to the CMP setup.
This is a separate run from DeepSeek V4.1 Flash on 4x CMP 170HX: Benchmark Results, which tested the CMP box on its own, with longer prompts and quality tests.
Setup
Both machines were raced at the same moment from one client with LLM-Super-Bench on 11 November 2026: 45 races each, none failed.
| 4x CMP 170HX | Mac Studio M5 Ultra | |
|---|---|---|
| Engine | vLLM 0.32.1rc1, tensor parallel 4 | Unsloth Studio v0.1.916-beta (llama.cpp) |
| Model build | DeepSeek-V4.1-Flash-1017, hybrid EXL3 + FP8 | DeepSeek-V4.1-Flash-1017, UD-Q2_K_XL (2-bit, Dynamic v3.1) |
| Engram tables | System RAM (about 189 GiB) | SSD |
| Requests at once | 8 | 4 |
| Context per request | 262,144 tokens | 65,536 tokens |
| Speculative decoding | DSpark, up to 7 draft tokens | None (no DSpark drafter loaded) |
Test settings, the same for both: thinking off, temperature 0, replies capped at 512 tokens, prompts taken from Mill's On Liberty and tagged so no cache could help. Prompt sizes were short (about 40 tokens), 4K and 16K, at 1, 2, 4, 8 and 16 users, 3 runs each.
Single-user speed
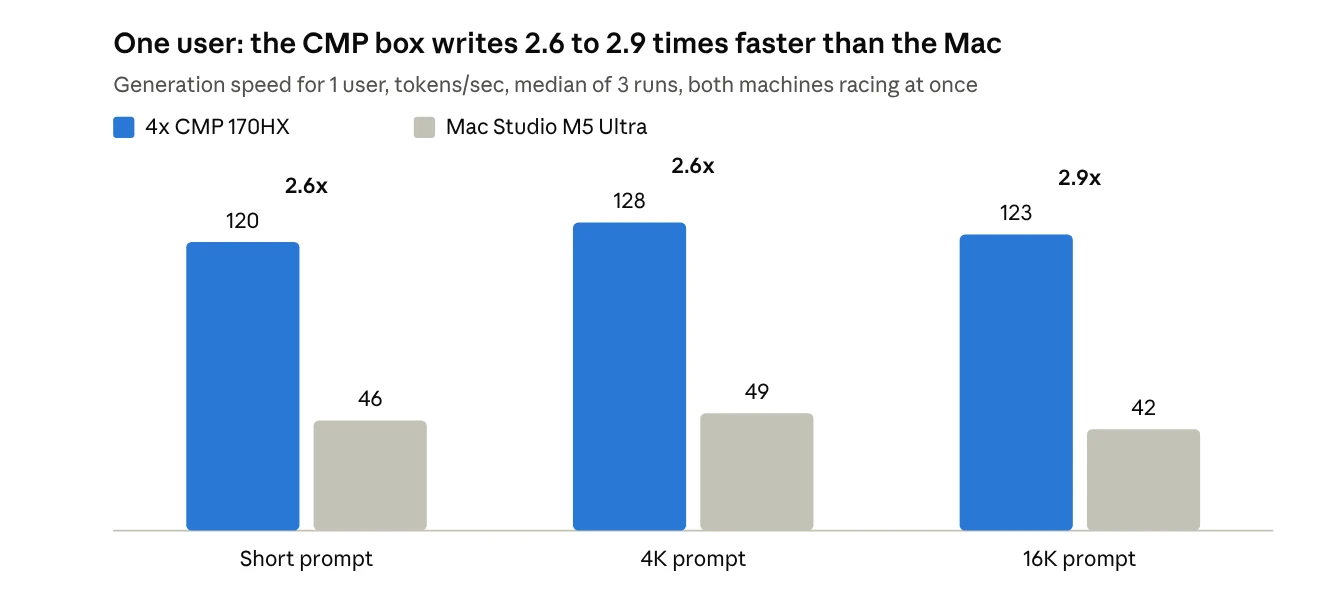
Once an answer starts, both machines hold their speed as prompts grow: the CMP box stays at 120 to 128 tokens/sec and the Mac at 42 to 49.
Prompt reading and waits
The biggest gap is before the answer starts: the CMP box reads a prompt about 6 times as fast, so a 16K prompt starts answering in 3.8 seconds instead of 26. With 16 users the queues even it out somewhat, down to a gap of under 3 times.
| Measure | 4x CMP 170HX | Mac Studio M5 Ultra | Gap |
|---|---|---|---|
| Prompt reading, 4K prompt (tokens/sec) | 3,579 | 587 | 6.1x |
| Prompt reading, 16K prompt (tokens/sec) | 3,785 | 561 | 6.7x |
| First word, 1 user, 4K prompt | 1.0 s | 6.1 s | 6.1x |
| First word, 1 user, 16K prompt | 3.8 s | 25.8 s | 6.8x |
| First word, 16 users, 4K prompts | 23.7 s | 69.6 s | 2.9x |
| First word, 16 users, 16K prompts | 90.6 s | 255.1 s | 2.8x |
Several users at once
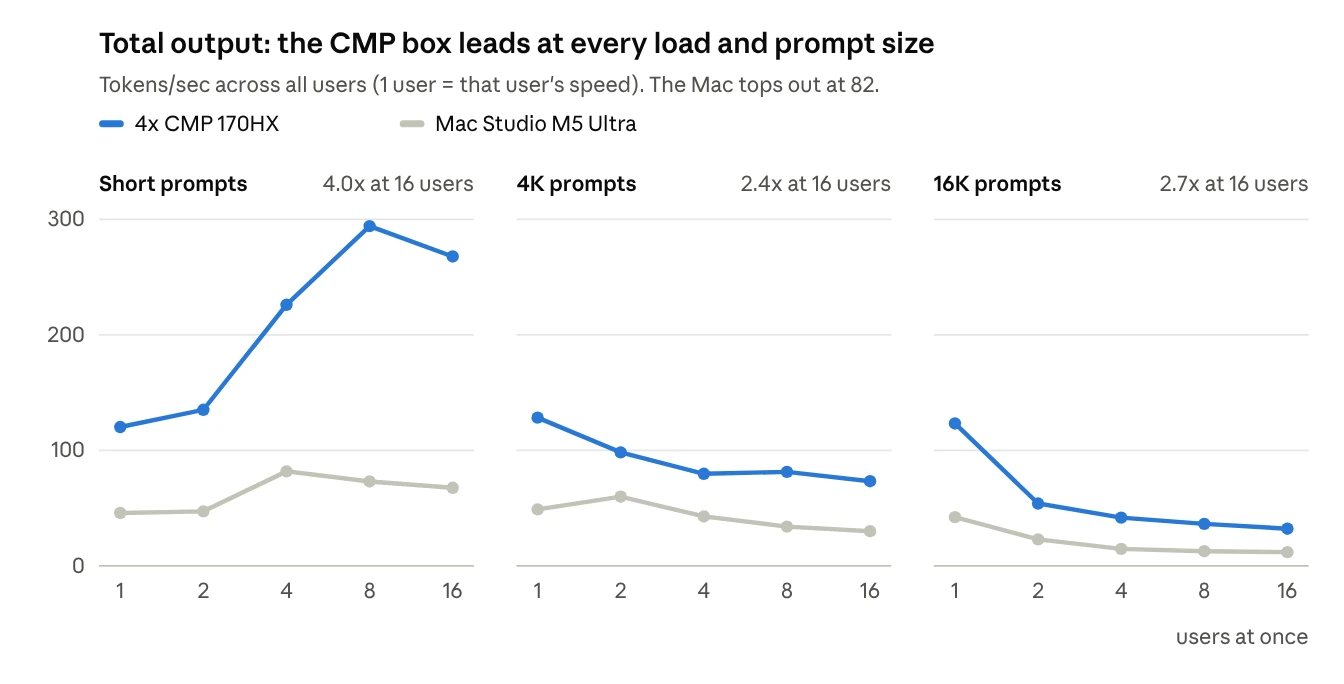
With short prompts the CMP box climbs to 294 tokens/sec at 8 users while the Mac peaks at 82 with 4. With 4K and 16K prompts both machines spend most of their time reading prompts, so adding users adds wait instead of output.
What this shows, and what it does not
- Two setups, not one file. The Mac's 2-bit build is smaller and lossier than the CMP box's EXL3 + FP8 build, and its Engram tables are read from the SSD instead of RAM. The Mac also ran without DSpark speculative decoding, which the CMP box had on; Unsloth puts DSpark's gain at 1.3 to 1.5 times decode speed.
- Queues shape the many-user results. The Mac serves 4 requests at once and the CMP box 8; past those points, extra users wait in line, which is why both curves flatten or drop.
- Racing both at once was fair. The CMP numbers match its solo run of 9 November within 4%, so sharing one client held neither machine back.
- Speed only, so far. This run covers prompts up to 16K, with no quality tests on the Mac yet.
Next: bringing the Mac closer to the CMP setup
The next run updates the Mac's Unsloth server to match the CMP box's configuration wherever the Mac can, then reruns the same tests. Two things cannot match on a 256 GB Mac: the weights and Engram tables together are too big for a higher-precision build or for Engram in RAM.
| Setting | 4x CMP 170HX | Mac, this run | Mac, next run |
|---|---|---|---|
| Speculative decoding | DSpark, up to 7 draft tokens | Off | DSpark, up to 7 draft tokens |
| Requests at once | 8 | 4 | 8 |
| Context per request | 262,144 tokens | 65,536 tokens | As large as memory allows |
| Prompt tokens per step | 2,048 | Default | 2,048 |
| KV cache | BF16 | Default | BF16 (or F16) |
| Engram tables | System RAM | SSD | SSD (no room in 256 GB) |
| Model build | Hybrid EXL3 + FP8 | 2-bit UD-Q2_K_XL | 2-bit (a closer build needs a 512 GB Mac) |
Unsloth's command line already has the DSpark switch, so the main change looks like this, with the slot, batch and cache settings added once they are confirmed:
unsloth run --model unsloth/DeepSeek-V4.1-Flash-1017-GGUF:UD-Q2_K_XL \
    --host 0.0.0.0 --port 8001 \
    --ctx-size 65536 \
    --speculative-type dspark --spec-draft-n-max 7 \
    --temp 1.0 --top-p 1.0 --min-p 0.0
After that run, this post gets the new Mac numbers beside the old ones, plus the long-prompt (32K and 64K) and quality tests on the Mac.
Related: DeepSeek V4.1 Flash on 4x CMP 170HX: Benchmark Results · Mac Studio vs. CMP 170HX: Same 27B Model, Same Settings · Race Your Local AI Machines and Trust the Numbers.