DeepSeek V4.1 Flash on 4x CMP 170HX: Benchmark Results
Nov 9, 2026 · Reclaimed Node · 5 min read
The short version
One user gets 111 to 129 tokens/sec from DeepSeek V4.1 Flash on four CMP 170HX cards, and that speed barely moves from a one-line prompt to a 115,000-token prompt. Prompts are read at about 3,600 tokens/sec, so a 128K prompt takes 34 seconds before the first word. The weak spot is several users with long prompts: they share that one prompt-reading rate, so waits grow in step with the number of users.
| Measure | Result |
|---|---|
| Single-user generation speed | 111–129 tokens/sec (short to 128K prompt) |
| Prompt reading (prefill) | 3,387–3,815 tokens/sec (4K to 128K) |
| Best total throughput | 296 tokens/sec (8 users, short prompts) |
| GSM8K maths | 96% (192/200) |
| MMLU-Pro knowledge | 86% (172/200) |
| IFEval instructions | 85% of prompts, 90.5% of rules |
| Long-context fact finding to 128K | 21/21 correct (16/21 in the strict format) |
Every race finished: 59 speed races and 521 quality questions, no errors.
Setup
One machine, run alone from NS-STUDIO with LLM-Super-Bench scripts/head-to-head.sh on 9 November 2026 (about 55 minutes). The Mac Studio side is still to come.
| Item | Value |
|---|---|
| Machine | thebeast: bare-metal Ubuntu, 4x CMP 170HX (64 GB each, unlocked), PCIe Gen2 x16 |
| Engine | vLLM 0.32.1rc1.dev515+ge05403fdc (Docker) |
| Model file | DeepSeek-V4.1-Flash-1017-hybrid-exl3-fp8 (the tool labels it FP8; it is a mixed EXL3/FP8 build) |
| Slots / context | 16 at once, 262,144 tokens per slot |
| Settings | Thinking off, temperature 0, reply cap 512 tokens (2,048 for quality) |
| Prompt text | Mill's On Liberty, each prompt tagged so no cache can help |
Tensor parallel size, --max-num-seqs and the speculative (DSpark/MTP) settings were not recorded with these results.
Single-user speed
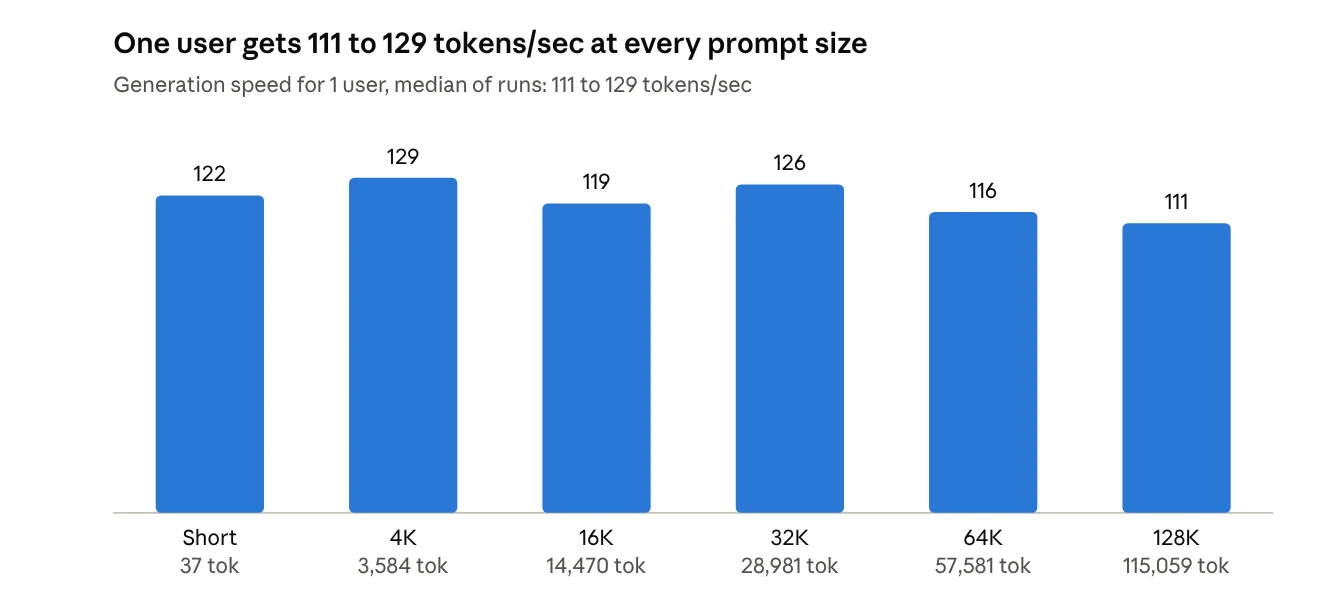
A long prompt costs time up front but no speed afterwards. The model uses about 16B of its 552B parameters per output token (vLLM recipe), which is why four 64 GB mining cards keep up.
Prompt reading
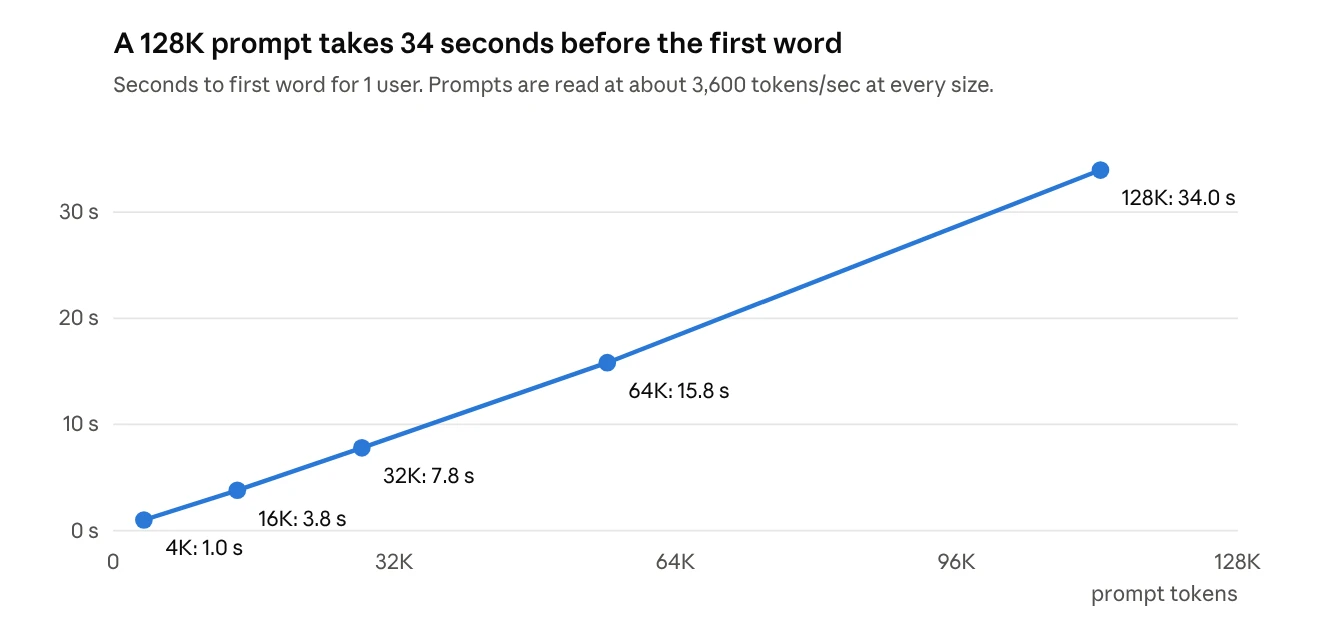
The wait grows in a straight line, about 0.28 seconds per 1,000 prompt tokens. Reading speed slips only at 128K (3,387 tokens/sec, against 3,600 to 3,800 below it).
Several users at once
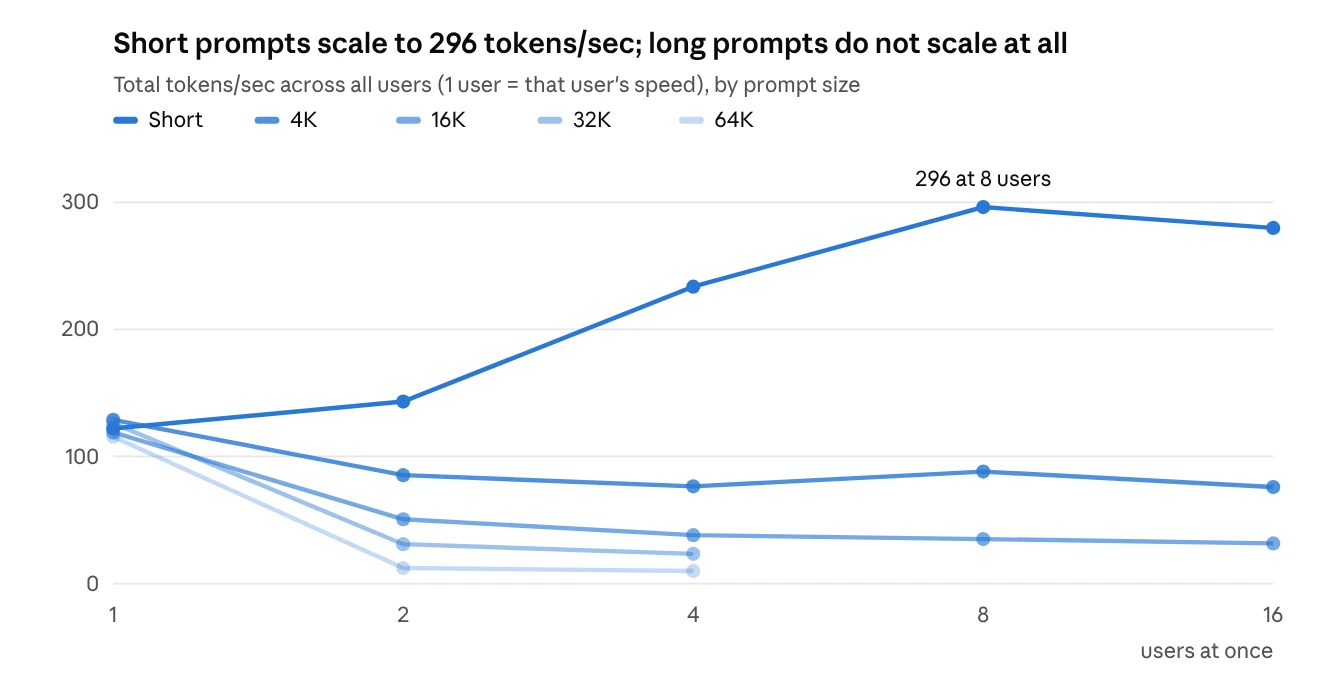
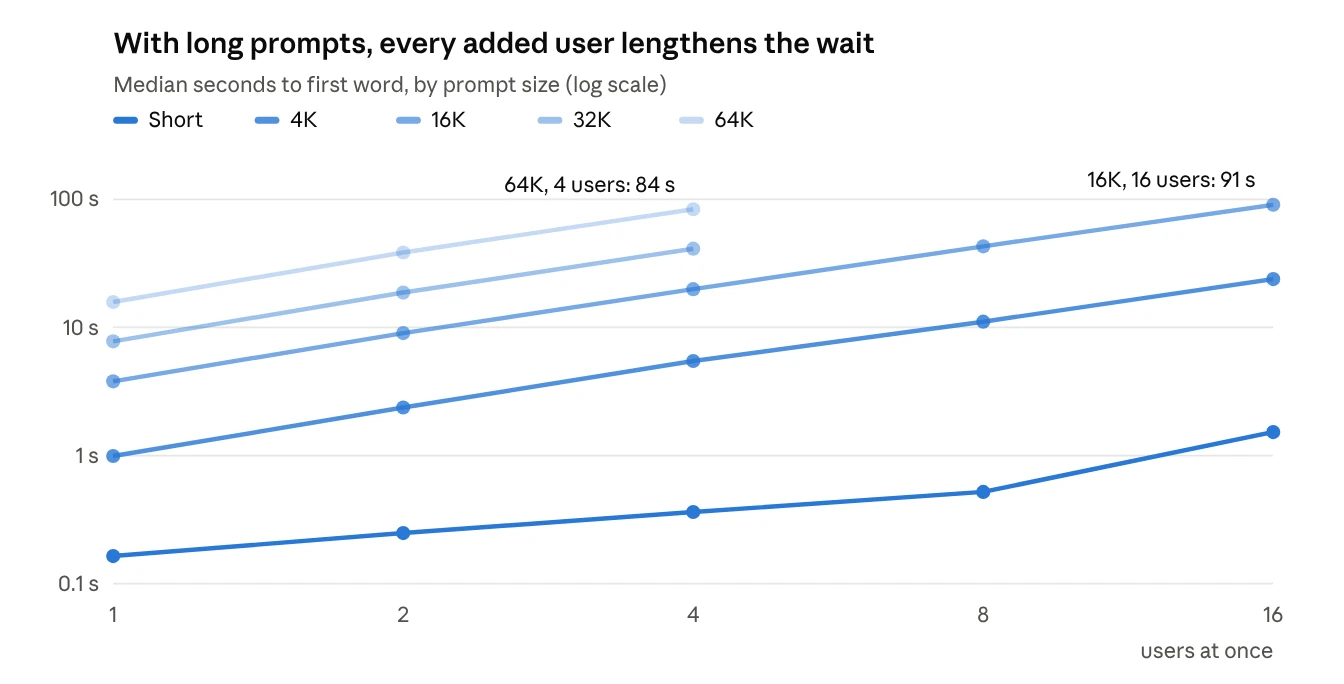
All users share one prompt reader of about 3,600 tokens/sec. Sixteen 4K prompts are 57,000 tokens to read, so the cards spend their time reading instead of writing, and total output stays near 80 tokens/sec. Short prompts avoid this: at 8 users the box writes 296 tokens/sec and each user still sees 46 tokens/sec.
Quality
This quantised build answers well with thinking off: 96% on grade-school maths and 86% on MMLU-Pro. Every test was zero-shot at temperature 0, so compare it with other machines run the same way, not with leaderboards.
| Test | Questions | Strict | Loose | Cut off at 2,048 tokens |
|---|---|---|---|---|
| GSM8K maths | 200 | 96.0% (192) | 96.0% | 0 |
| MMLU-Pro knowledge, 14 subjects | 200 | 86.0% (172) | 86.5% | 5 |
| IFEval following instructions | 100 | 85.0% of prompts, 90.5% of rules | 87.0% of prompts | 1 |
| Long context, 8K / 32K / 128K | 21 | 76.2% (16) | 100% (21) | 0 |
- Long context: needle and multi-key lookups were perfect at every size, 128K included. The five strict misses are all variable-chain answers with the right values, listed one per line or with commas instead of the format the checker wants.
- MMLU-Pro by subject: weakest were engineering (10/16), psychology (8/13) and law (14/18); biology, history, philosophy and computer science were perfect. With 6 to 23 questions per subject, treat these as hints, not rankings.
- Cut off: six answers hit the 2,048-token cap. Raising
Q_TOKENSwould recover a point or two.
Takeaways and next steps
Four mining cards run a 552B-parameter model at over 110 tokens/sec for one user, at any prompt length up to 128K. The limit is shared prompt reading: once a second user with a 4K+ prompt joins, each person waits longer and total output does not rise.
- Record the server settings (tensor parallel,
--max-num-seqs, DSpark/MTP settings) with the results, so the numbers say how the server was started. - Try a vLLM tuning pass for long-prompt concurrency: a larger
--max-num-batched-tokensor a lower--max-num-seqsmay trade per-user speed for shorter waits. Re-run./scripts/head-to-head.sh speedto compare. - Mac Studio side: run the same script with
MACHINES="Mac Studio M5 Ultra"once a DeepSeek V4.1 Flash build is loaded in oMLX, and compare the two result sets. The 256 GB Mac needs a 2-bit build, so say so beside its numbers; the 512 GB Mac Studio could run a closer match. - More tests: a multi-turn agent test and a cache-reuse test, which LLM-Super-Bench does not have yet.
Related: Four CMP 170HX Cards, One Server: 256GB of VRAM · Same Model, Three Engines: vLLM Puts the CMP 170HX Ahead · Race Your Local AI Machines and Trust the Numbers.